Publications / 论文

You can also find my articles on my Google Scholar profile.

* Equal contribution.
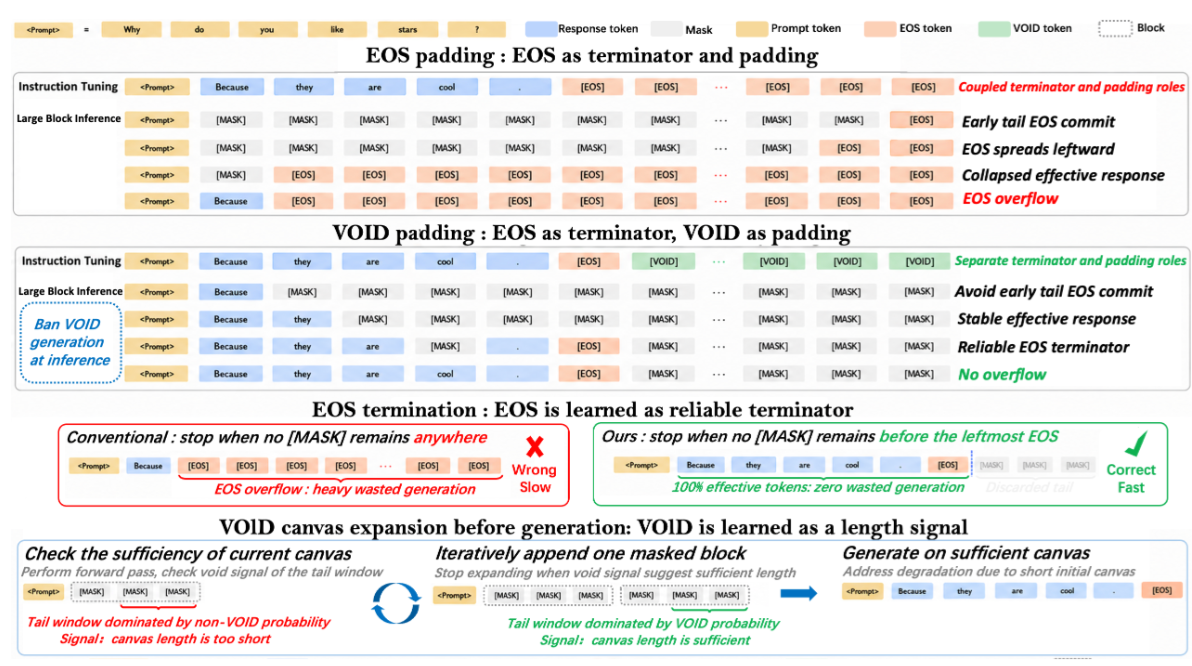
COLM VoidPadding: Let [VOID] Handle Padding in Masked Diffusion Language Models so that [EOS] Can Focus on Semantic Termination paper thumbnail

VoidPadding: Let [VOID] Handle Padding in Masked Diffusion Language Models so that [EOS] Can Focus on Semantic Termination

Chunyu Liu, Zhengyang Fan, Kaisen Yang, Alex Lamb
COLM 2026 Workshop on Efficient Reasoning (Spotlight), 2026
ArXiv JustQuant: You Don't Need Smoothing, SVD, or Rotation for 4-Bit Activation Quantization paper thumbnail

JustQuant: You Don't Need Smoothing, SVD, or Rotation for 4-Bit Activation Quantization

Kaicheng Yang*, Kaisen Yang*, Chunyu Liu*, Xianglong Yan, Haotong Qin,
ArXiv preprint, 2026
ArXiv Frozen in a Frame: The Velocity Blind Spot in JEPA World Models paper thumbnail

Frozen in a Frame: The Velocity Blind Spot in JEPA World Models

Tinghe Zhang, Chunyu Liu, Yu Leon Liu, Zerui Zhao, Jiaheng Chen,
ArXiv preprint, 2026
COLM Understanding Is Done Early: A Depth Division of Labor in Large Language Models and Its Use for Unbounded-Context Memory paper thumbnail

Understanding Is Done Early: A Depth Division of Labor in Large Language Models and Its Use for Unbounded-Context Memory

Hanzuo Liu, Xuan Qi, Chunyu Liu, Haotian Zhong, Yulong Wang,
COLM 2026 Workshop on Efficient Reasoning, 2026
ArXiv A Survey of Efficient Attention Methods: Hardware-Efficient, Sparse, Compact, and Linear Attention paper thumbnail

A Survey of Efficient Attention Methods: Hardware-Efficient, Sparse, Compact, and Linear Attention

Jintao Zhang, Rundong Su*, Chunyu Liu*, Jia Wei*, Ziteng Wang*,
ArXiv preprint, 2025